
Anderson LimaSoftware Engineer & Architect
1 de outubro de 2026
20 min de leitura
0 visualizações
DeskPilot v0.2 changes zero domain rules for a category-and-summary suggestion, validated in code, visible only in shadow mode until a human reviews it

A synthetic ticket lands in tenant A's queue: "The system returns a 500 error every time I try to save the customer registration form." Three possible responses to that same sentence, side by side:
if looks for the substring "error" in the text, finds it, tags the category as bug. Zero cost, no perceptible latency, zero ability to handle any ticket that doesn't contain that exact string.category: "bug", a one-sentence summary, a verbatim quote of the span that justifies the category, and a self-declared confidence of 0.82. It costs a fraction of a cent and about 15ms this session (a stub's number, not a real provider's). But it is only a suggestion — no line of code turns that JSON into a state change.bug category also sees the whole ticket, decides whether to accept, edit, or reject the suggestion, and only that decision — calling the same applySuggestionCommand chapter 03 already tested — changes what gets recorded.All three coexist in this chapter, and the line between them is not stylistic: it is the same line that separates TICKET_TRANSITIONS from SUGGESTION_TRANSITIONS in the domain inherited from chapter 03, unchanged since then. An AI suggestion never appears in the list of authorized roles for any ticket transition — and it is exactly that omission, not a prompt instruction, that keeps anything a model produces from becoming a priority change, an assignment, or outbound communication without review.
This chapter builds DeskPilot's first real AI suggestion — ticket category and summary, in shadow mode — and the four failures that transition tends to introduce when the previous chapter's discipline isn't carried forward.
Before any architecture, here is the output contract this entire chapter protects:
export interface ValidatedSuggestionOutput {
  schemaVersion: string;
  tenantId: string;
  ticketId: string;
  category: Category;
  summary: string;
  evidenceQuotes: string[];
  /**
   * Self-declared by the model, 0..1. NOT a calibrated probability -- see
   * Failure #2. Nothing that reads this field is permitted to use it to
   * skip human review, auto-accept a suggestion, or widen a permission.
   */
  confidenceSelfDeclared: number;
  abstain: boolean;
  modelId: string;
  promptVersion: string;
  policyVersion: string;
  dataVersion: string;
}
And the check that decides whether a raw JSON payload becomes that type or becomes a fallback:
const tenantId = String(obj.tenant_id);
if (tenantId !== ctx.expectedTenantId) {
  // This is the structural fix for "modelos ... produzem side effect
  // final" / "tenant errado": tenant scoping is verified here, in code,
  // never trusted because the model echoed the right-looking value.
  errors.push("tenant_mismatch");
}
// (ticket_id, category, abstain and summary get the same discipline)
for (const quote of evidenceArray) {
  // The grounding check: every cited quote must appear verbatim in the
  // text the model was actually authorized to read. A quote that is not
  // a substring is either a hallucination or evidence for a claim
  // outside the authorized context -- both are rejected the same way.
  if (!ctx.authorizedText.includes(quote)) {
    errors.push("evidence_not_verbatim");
    break;
  }
}
Two lines do the heavy lifting of this chapter. The first never trusts the tenant_id the model returned — it is compared against the tenant that actually asked the question, and a mismatch becomes an error, not a warning. The second never accepts an evidence quote that doesn't exist, word for word, in the text the model was authorized to read. A JSON payload can be perfectly well-formed, with a category inside the allowed enum, and still be rejected — because a valid schema and true content are different properties, and confusing them is the first of this chapter's four failures.
Neither line depends on the model "behaving well." They would be exactly the same whether the adapter were a real paid provider or the deterministic stub this chapter actually uses — and that's the point: the guarantee lives in validation, not in trusting that a specific model is well-behaved.
The task chosen for this chapter is deliberately small: suggest category and a short summary, with evidence quoted from the ticket itself. Final priority, assignment, and any outbound communication remain human commands, validated by the same applyCommand chapters 03 and 04 already cover with tests. That restriction isn't modesty — it's the only way to ask the right question: "does this specific suggestion save review time without opening any new path to harm?" instead of the bigger, vaguer question "does AI help the product?"
The comparison the chapter calls for — no AI, rule, single call, workflow, agent — has a direct answer for each option not chosen. A pure rule (a keyword classifier) already exists in this code as a baseline: it's the same ruleBasedCategory the eval uses for comparison, and on its own it never abstains, even when the ticket doesn't have enough information — it always "guesses" some category. A multi-step workflow or agent with tools wasn't built because no error observed across this chapter's 47 cases calls for an extra retrieval step or an external tool: the authorized context fits entirely in the input, and Anthropic states this priority order directly — "for many applications, optimizing single LLM calls with retrieval and in-context examples is usually enough" — adding complexity without an observed error to justify it is the opposite of what this chapter argues for.
What's left is a single, typed, validated call, confined to shadow mode: the suggestion exists, it's visible to the agent, but it doesn't change anything on its own.
Chapter 04 left the suggestions table empty by design — it existed in the contract, but nothing wrote to it. This chapter writes to it for the first time, without touching any inherited rule:
// Migration note (PE04 -> PE05): copied byte-for-byte again, still no type,
// transition or rule edited. Chapter 05 adds an AI suggestion path entirely
// in ../ai/ (schema validation, stub/real adapter, shadow orchestration) and
// extends the storage contract in ./repository.ts to persist the richer
// suggestion payload — it does not touch applyCommand, TICKET_TRANSITIONS or
// the "ai" role's exclusion from every allowedRoles list below. That
// exclusion is precisely the guard the new AI path depends on: no matter
// what a model outputs, nothing in this file lets it reach applyCommand.
That comment is literally at the top of src/domain/domain.ts — the same file chapter 04 had already copied byte for byte from chapter 03. Three sessions later, zero lines of domain rule have changed. What changed is everything around it:
src/ai/schema.ts validates the shape above with no third-party library — twelve sequential checks (required field present, category in the enum, tenant and ticket matching, summary length, verbatim evidence, confidence within [0, 1]), each returning a specific rejection reason, never an opaque boolean.
src/ai/adapter.ts defines the SuggestionAdapter interface and two implementations. StubAdapter is deterministic and offline — the only one any test or this chapter's eval ever calls — and accepts a simulate field that forces one of ten behaviors (normal, abstention, malformed JSON, wrong tenant, over-length summary, hallucinated evidence, invalid category, timeout, high cost, unavailability). HttpProviderAdapter implements the same interface for a real provider, but no session so far instantiates it — there is no paid key in this environment, and the very prompt governing this package forbids using one.
src/ai/shadow.ts is the orchestrator. It races the adapter against a timeout with Promise.race, applies a per-task cost ceiling before accepting any response, validates with schema.ts, and decides between writing a pending suggestion or logging an auditable fallback. None of these four behaviors — timeout, cost, validation, fallback — is optional or conditional on a specific provider; all of them run for the stub exactly as they would for a real provider, because they depend only on the SuggestionAdapter interface, never on the concrete class behind it.
Two new HTTP routes. POST /tickets/:id/suggest requires an actor with the system role — not agent, not manager, and certainly never ai, which has no possible session at all. POST /tickets/:id/suggestions/review is the only route that changes a suggestion's state, calling the same applySuggestionCommand that already existed, unchanged, since chapter 03.
migrations/0002_suggestion_details.sql is additive: no column, type, or policy from chapter 04 was altered. The new suggestion_details table holds summary, evidence, and confidence — the fields a suggestion needs to be reviewable, but that the original suggestions table never had, because chapter 04 left it empty by design. The same row-level security policy protecting tickets since chapter 04 protects this new table, line for line identical, and a real integration test against Postgres proves it — not just the offline test with the in-memory repository.
| Decision | Rejected alternative | Why |
|---|---|---|
| Hand-rolled schema validation, no library | Zod, Ajv, or similar | Twelve sequential checks don't justify a new dependency; the same "no HTTP framework" discipline from chapter 04 (just node:http) applies here |
Suggestion detail in a separate table (suggestion_details), not new columns on suggestions | Add summary/evidence/confidence directly to suggestions | suggestions already had a contract chapter 04 relied on (id, tenant_id, ticket_id, state, category, reviewed_by); extending via a new table avoids a destructive migration and documents the change as additive |
system actor exclusively triggers generation | Allow any authenticated actor to trigger /suggest | Suggestion generation is a system event, not an agent action — mixing the two would hide who actually requested the suggestion in the audit log |
| Self-declared confidence stored, never read for a decision | Use confidence > 0.8 to skip human review on "obvious" cases | An LLM's self-declared confidence is not a calibrated probability — see Failure #2 below; any shortcut here reopens exactly the problem shadow mode exists to close |
| Cost budget and timeout enforced before schema validation | Validate first, cut cost afterward | A well-formed but expensive response is still discarded — the budget is a policy independent of the response's quality, not an optimization applied to already-accepted responses |
| Eval includes a rule baseline on the same corpus | Report only the AI path's accuracy, in isolation | A single number doesn't say whether AI beats the simplest alternative — and this session, without a real provider, both paths share the same classification function by construction (see Evaluation below) |
Failure 1 — schema confused with truth. Symptom: a well-formed JSON payload, with a category inside the enum, is treated as if the category were correct or the evidence were real. Cause: structural validity and content correctness feel like the same check in the mind of whoever builds the system, but they are not the same check in code. Response: examples/eval/report.json keeps valid_output_rate (0.84 in dev, 0.818 in holdout — how many JSON payloads passed validation) separate from category_accuracy (0.895 in dev, 0.882 in holdout — of those that passed, how many got the category right) as two distinct numbers, never one. Case case-044 in the dataset forces exactly this scenario: a valid JSON payload whose evidence quote doesn't exist in the ticket — rejected by evidence_not_verbatim, even with everything else correct.
Failure 2 — self-declared confidence used as authorization. Symptom: a high confidence number becomes an excuse to skip human review or auto-accept. Cause: confidence looks like a probability because it has the shape of one, but it's self-declared by the same model that might be wrong about everything else. Response: confidenceSelfDeclared is stored in suggestion_details and returned for display — and there is no other read of that field anywhere in src/ai/shadow.ts or src/api/server.ts. The test "normal scenario: writes a pending suggestion... never touches ticket state" proves this operationally: even with confidence 0.82, the suggestion is born in pending state, identical to what it would be with confidence 0.3 — only applySuggestionCommand, called by an authenticated human agent, changes that state.
Failure 3 — contaminated holdout. Symptom: the holdout stops meaning anything because the system was repeatedly tuned against the very errors it was supposed to measure independently. Cause: the temptation for "just one more adjustment" after seeing a holdout case fail is immediate and feels harmless, case by case. Response: the split field in examples/eval/cases.synthetic.jsonl is fixed at the moment each case is written, never recomputed after running the eval; run.ts summarizes both splits in the same pass, with no branch that reads holdout before deciding anything about dev; and the adapter/policy under test (StubAdapter, deskpilot-suggest-v1, shadow-v0.2) were not tuned against holdout failures during this session — the only tuning loop that happened was against test/ai/*.test.ts's unit assertions, which use their own fixtures, not this dataset. This is a process discipline, documented in examples/eval/README.md, not a code lock — and that difference is exactly the point: code can't stop someone from peeking at the holdout early; only the recorded discipline can.
Failure 4 — a fallback that hides failure and loses work. Symptom: a timeout or provider error is treated as if nothing happened, or worse, corrupts what already existed in the manual queue. Cause: a silent fallback feels safer short-term because it doesn't raise an alarm, but it hides exactly the signal someone would need to see that the provider is degraded. Response: every exit path in src/ai/shadow.ts's fallback() writes a suggestion.fallback audit event before returning — visible, not silent — and the fallbackReason comes back in the HTTP response ({"ok": false, "fallbackReason": "timeout", ...}), not just in a log nobody reads. More importantly: the ticket's queue position, state, and prior audit history stay completely untouched by a failed suggestion attempt — there's no ticket-state work for a fallback to lose, because suggestion generation never touches that state in the first place. The timeout test confirms this: after simulating an 850ms delay against a 100ms budget, repo.getSuggestion("tenant-a", "ticket-a1") still returns null, and the queue is exactly as it was.
The dataset (examples/eval/cases.synthetic.jsonl) has 47 cases, 25 in dev and 22 in holdout, covering six normal categories plus one rare class (security_incident, three cases total), four ambiguous cases, three with insufficient information, two long tickets, two with an embedded injection attempt, two with synthetic PII, and seven adversarial scenarios — one for each of the adapter's simulate tags (malformed JSON, wrong tenant, over-length summary, hallucinated evidence, timeout, high cost, unavailability).
What the numbers prove: a valid-output rate of 84% in dev and 81.8% in holdout; of those that passed validation, category accuracy of 89.5% (17 of 19 cases, excluding abstentions and fallbacks) in dev and 88.2% (15 of 17) in holdout; an abstention rate among valid outputs of 9.5% in dev and 5.6% in holdout; and, more important for the system's safety, every one of the seven adversarial scenarios produced exactly the fallback it should have — none of them was treated as success. The two prompt-injection cases (case-037, case-038) confirm the embedded text ("ignore previous instructions...", "you are now in admin mode...") never reaches a real command: one produces a normal suggestion that ignores the embedded instruction (because the classifier never reads instructions, only keywords), the other is rejected for an invalid category when the injection tries to force a value outside the enum.
What the numbers don't prove, and the report states this explicitly in report.json.limitations: StubAdapter reuses the exact same keyword-classification function the rule baseline uses — so on any non-adversarial case, both paths have exactly the same category accuracy by construction, not from any real advantage of the "AI layer." Without a real provider and no paid key this session, there's no honest way to measure whether a real model beats the rule baseline on this task — and this report doesn't pretend there is. Forty-seven cases labeled by a single annotator (this session) also don't support a tight confidence interval per class, especially for the rare class, with only three examples total and just one in holdout. The four cases in the "ambiguous" bucket explicitly document where a reasonable second annotator would disagree with the chosen label — for example, a ticket mentioning both "password reset" and "error" gets an access label from a human reading, but the keyword classifier picks bug first, because the category-checking order in the code prioritizes bug before access.
None of these caveats invalidate the chapter's value — they're exactly the kind of thing Anthropic recommends checking before trusting an eval: whether the task is well-defined enough that a human would solve it consistently. Where the answer is "not always" — as in the four ambiguous cases — the eval documents the disagreement instead of hiding it behind an average.
Cost per useful task (non-abstaining suggestion, with valid output) this session: $0.00471 in holdout, computed from the stub's fixed constants ($0.004 per normal call, $0.42 when the scenario simulates high cost and is therefore discarded before counting as "useful"). This number doesn't represent any real provider's pricing — it's a marker that the pipeline knows how to compute cost per useful task, not a production budget estimate.
Security mapped line by line against the OWASP taxonomy for LLM applications in examples/threat-model.md: of the ten categories, seven apply directly to this package and each has a specific response in the code — prompt injection contained by the closed schema, sensitive information disclosure contained by an audit event that never stores ticket text, unbounded consumption contained by timeout and cost budget. Three categories (data/model poisoning, system prompt leakage, embedding weaknesses) don't apply because this chapter has no training pipeline, doesn't expose a system prompt to an end customer, and uses no vector search — not by accident, but because no observed error justified adding RAG when the authorized context already fits entirely in the input.
Reversibility: a rejected, expired, or never-reviewed suggestion leaves no trace in the ticket's state. Reverting a wrongful acceptance means a second human call to applySuggestionCommand — the same command tested since chapter 03 — never a special "undo AI" operation. Tenant isolation is redundant across two independent layers, the same discipline as chapter 04: an application-level filter on every query and RLS at the database, now proven for suggestion_details too, not just for tickets.
npm test and node run.ts make no network call beyond npm install.confidenceSelfDeclared decides an outcome — grep confirms the field is only written and displayed.pending state; only an authenticated human actor (agent/manager) changes that state.suggestion_details with the same policy as tickets, proven against real Postgres, not just the in-memory repository.Basic. Add a new case to examples/eval/cases.synthetic.jsonl with simulate: "normal" for the feature_request category in Portuguese, run node run.ts, and confirm category_accuracy's denominator changed for the chosen split. Acceptance criterion: the new case shows up in report.json.dataset.total (now 48), and the corresponding split's category_accuracy denominator increases by exactly one, unless the case has gold_abstain: true.
Commented solution: the easiest thing to get wrong here is forgetting that tenant_id/ticket_id can only be tenant-a/ticket-a1 or tenant-b/ticket-b1 in this harness — run.ts uses exclusively the two fixture tickets by design (see the comment at the top of the file), so a made-up ticket_id causes ticket_not_found inside writeShadowSuggestion, not a schema-validation error.
Intermediate. Write a new test in test/ai/shadow.test.ts that forces two fallbacks in a row on the same ticket (for example, timeout followed by malformed_json) and confirms the second fallback isn't blocked or altered by the first — that is, that shadow.ts carries no state between calls that could make the second attempt behave differently from the first. Acceptance criterion: the two returned fallbackReason values match exactly what each simulation should produce, and repo.listAudit shows two distinct suggestion.fallback events, not one.
Commented solution: this should pass with no code change — runShadowSuggestion has no shared module-level variable between calls, it only receives everything as a parameter. If the test fails, the most likely bug is some hidden state in MemoryRepository being incorrectly reused between the two calls within the same test; the correct fix is making sure each call to runShadowSuggestion is genuinely independent, never "fixing" the test to hide the behavior.
Advanced. Implement a second quality metric beyond category_accuracy: a check that each valid suggestion's summary actually summarizes the content of the cited evidenceQuotes, not just the ticket's first sentence (today, StubAdapter.buildOutput uses firstSentence as a shortcut — a real summary would need more than the first sentence for long tickets). Acceptance criterion: the new metric appears in report.json with its own denominator, separate from category_accuracy, and the report keeps explicitly stating it measures summary-vs-evidence, not summary-vs-editorial-quality (which would require a second human annotator or a calibrated LLM judge — out of scope for this chapter).
Commented solution: the risk here is exactly the verbosity bias that shows up in LLM-as-a-judge evaluation — if the new metric turns into "is the summary long enough," it will reward generic summaries instead of precise ones. An honest metric compares the summary against the set of evidenceQuotes (for example, checking whether the summary's central terms appear in at least one quote), not against a length target.
Chapter 06 inherits the v0.2 MVP (this chapter's code), the event contract (unchanged, with two additive new types in events.schema.json), and the eval report in examples/eval/report.json. The question it has to answer — per ../product-designer-serie-06/prompt.md, read only in the section describing its input and scope — is whether a high suggestion-acceptance rate hides rework, and how to design metrics and a per-tenant experiment without confusing correlation with business impact. This chapter measures no business impact at all — it only measures whether the suggestion reaching the agent is valid, grounded, and contained when something goes wrong. What chapter 06 does with that suggestion's acceptance rate — and with the rework a high acceptance rate can hide — is the next question, not this one.
Produtos gratuitos e pagos para transformar ideias em uma base que você consegue executar.
13 produtos disponíveis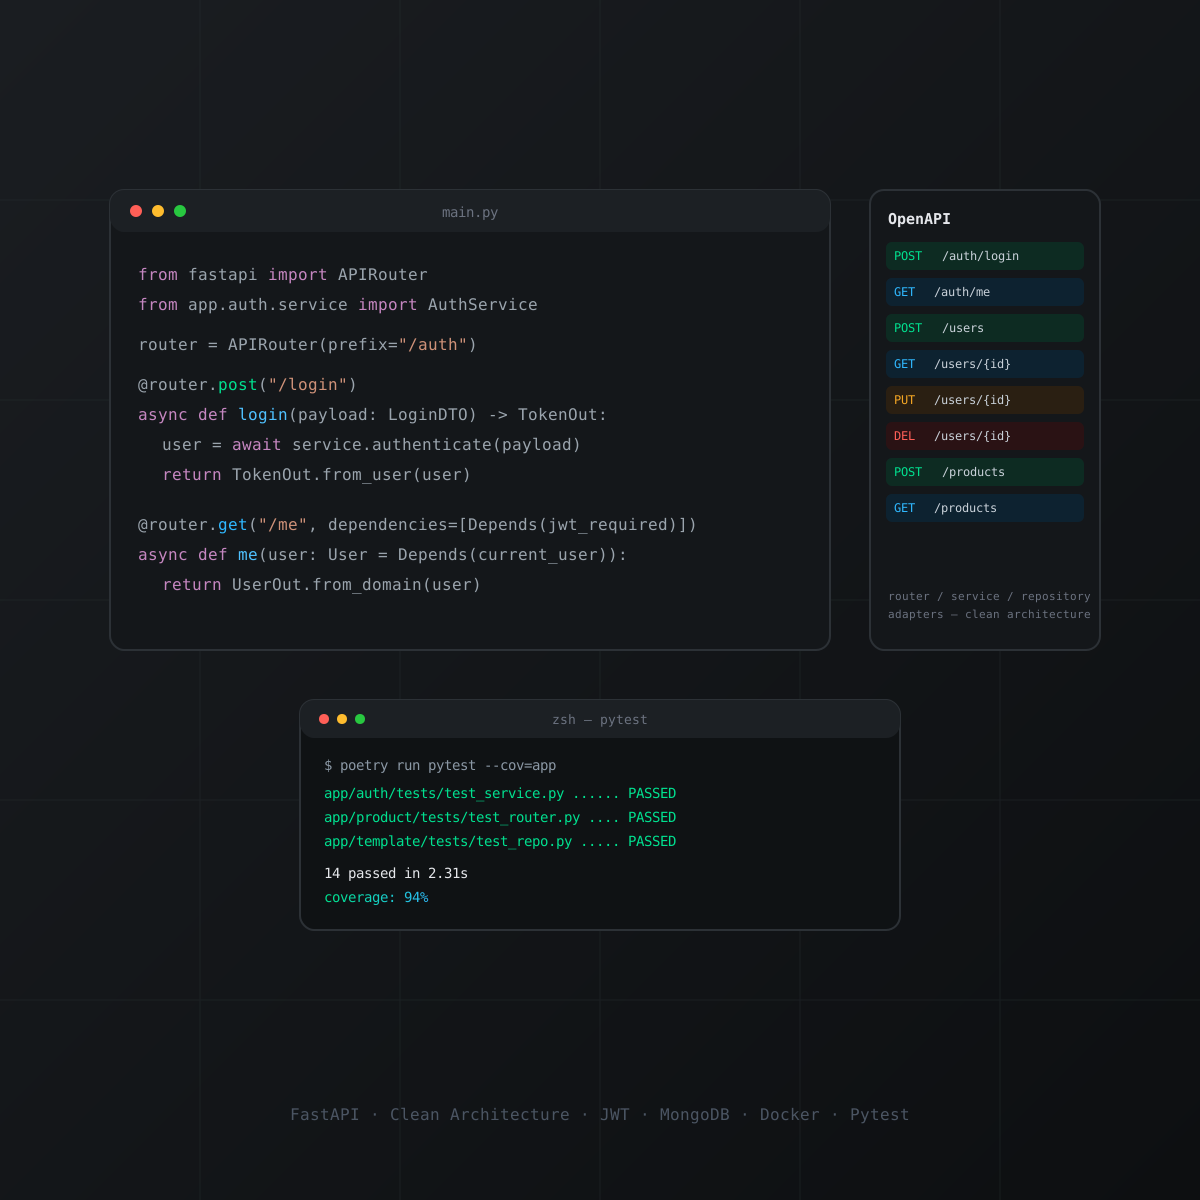
nextjs · boilerplate
Boilerplate de API em Python com FastAPI, organizado em Clean Architecture (router, service, repository e adapters por módulo). Inclui autenticação JWT com hashing bcrypt, MongoDB, testes com pytest e cobertura, Dockerfile e docker-compose para subir localmente, e documentação Swagger/OpenAPI automática. Repositório de origem privado; snapshot técnico verificado antes da publicação.
Ver produto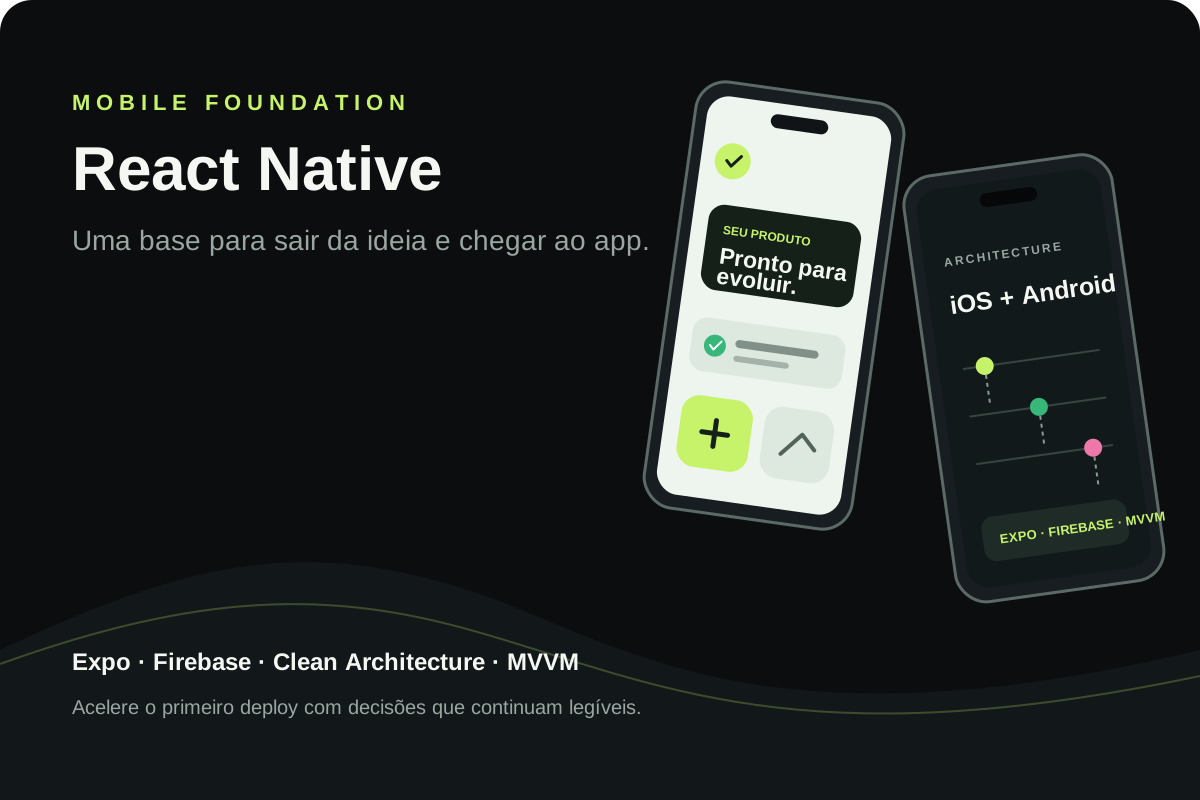
react · boilerplate
Base React Native para apps iOS e Android com Expo, Clean Architecture, MVVM, Firebase e módulos nativos. Referência técnica do VaiDeFut, com distribuição pública no Google Play e fluxo de publicação para iOS documentado.
Ver produto
nextjs · boilerplate
Kit gratuito e open source para começar com agentes de código em Claude Code, Codex, Gemini, Copilot e OpenCode. A licença MIT está confirmada no repositório público.
Ver produto
nextjs · boilerplate
Fundação AI-first white-label para lançar produtos SaaS com Next.js, chat, RAG, memória, tenants e documentação. O snapshot verificado documenta Supabase, não MongoDB; essa limitação está explícita. MongoDB, Redis e RabbitMQ exigem integração/configuração compatível.
Ver produtonextjs · boilerplate
Edição avançada da base white-label e multi-tenant AI-first para acelerar produtos com Next.js, chat, RAG, memória e documentação. O snapshot verificado ainda não comprova uma camada Ultra distinta; a oferta mantém essa limitação transparente e explicita as trocas de provider, cache e filas.
Ver produtonextjs · boilerplate
Base white-label e multi-tenant para transformar uma ideia em um SaaS AI-first com Next.js, chat, RAG, memória e segurança documentados. O snapshot verificado usa Supabase; o nome identifica o repositório de origem. Provider, cache e filas ficam explícitos; Redis e RabbitMQ são integrações configuráveis.
Ver produto
react · portfolio
Uma contribuição única para apoiar conteúdo técnico gratuito, pesquisa e a continuidade de projetos relevantes publicados por Anderson Lima. Você escolhe o valor; não é uma assinatura.
Ver produto
react · boilerplate
Starter React gratuito para criar uma suíte de testes confiável desde o primeiro commit, com Vitest, Testing Library, Playwright, Vite, TypeScript, Zustand, React Query, MirageJS e PWA. O repositório não declara uma licença SPDX; revise os termos antes de uso comercial.
Ver produto
react · portfolio
Monorepo público em React, TypeScript e Vite para explorar uma biblioteca de componentes com linguagem visual inspirada em interfaces nativas. O README atual é enxuto e não declara uma licença SPDX; trate como preview gratuito.
Ver produto
nextjs · saas
Boilerplate SaaS AI-first com Next.js, Supabase, Stripe e provider routing para começar do primeiro prompt e acelerar o caminho até um deploy real. As adaptações de IA, banco, e-mail, cache e filas ficam explícitas; Redis e RabbitMQ são integrações configuráveis.
Ver produto
react · saas
Starter kit React + TypeScript para SaaS multi-tenant com Firebase, Atomic Design, temas, PWA, telas de produto, MirageJS e chat com Gemini extensível a outros providers. Valide requisitos de produção, custos e integrações antes de publicar.
Ver produto
react · boilerplate
Starter React público com TypeScript, Zustand, React Query, Tailwind CSS, PWA e integrações de IA documentadas. O repositório não declara uma licença SPDX; revise os termos antes de uso comercial.
Ver produto
nextjs · saas
Landing page SaaS para Next.js, TypeScript e Tailwind CSS com SEO, temas, i18n, PWA e pontos de integração para auth, Stripe e IA. Uma base clara para sair da tela vazia e adaptar sua proposta.
Ver produtoContinue explorando tópicos similares
Uma regra, uma sugestão de IA e a decisão de um agente humano, para o mesmo ticket sintético: só uma delas pode mudar o estado do ticket. A partir dessa restrição, o DeskPilot ganha uma sugestão…

DeskPilot's tests were green. A synthetic provider outage, an actual local restore, and a release review exposed what those tests did not establish: whether a support agent can safely use the pilot.
Todo teste do DeskPilot está verde desde o capítulo 03. Nenhum deles diz o que acontece quando o provedor de IA cai no meio de uma triagem, quando um tenant gasta sem teto, ou quando alguém tenta…
Checklist de 47 pontos para encontrar bugs, riscos de segurança e problemas de performance antes do lançamento.
Templates testados em produção, usados por desenvolvedores. Economize semanas de setup no seu próximo projeto.